On this page · 11 sections
- What Supabase announced, and the status of each piece
- How agent-ready local development works
- What Declarative Schemas 2.0 and pg-delta do
- What Supabase Compute is, and whether you can use it
- How the MCP server for your app works
- How to secure an app MCP server
- What this means for Flutter and mobile teams
- Should you adopt these features now?
- Open questions
- How eCorpIT can help
- References
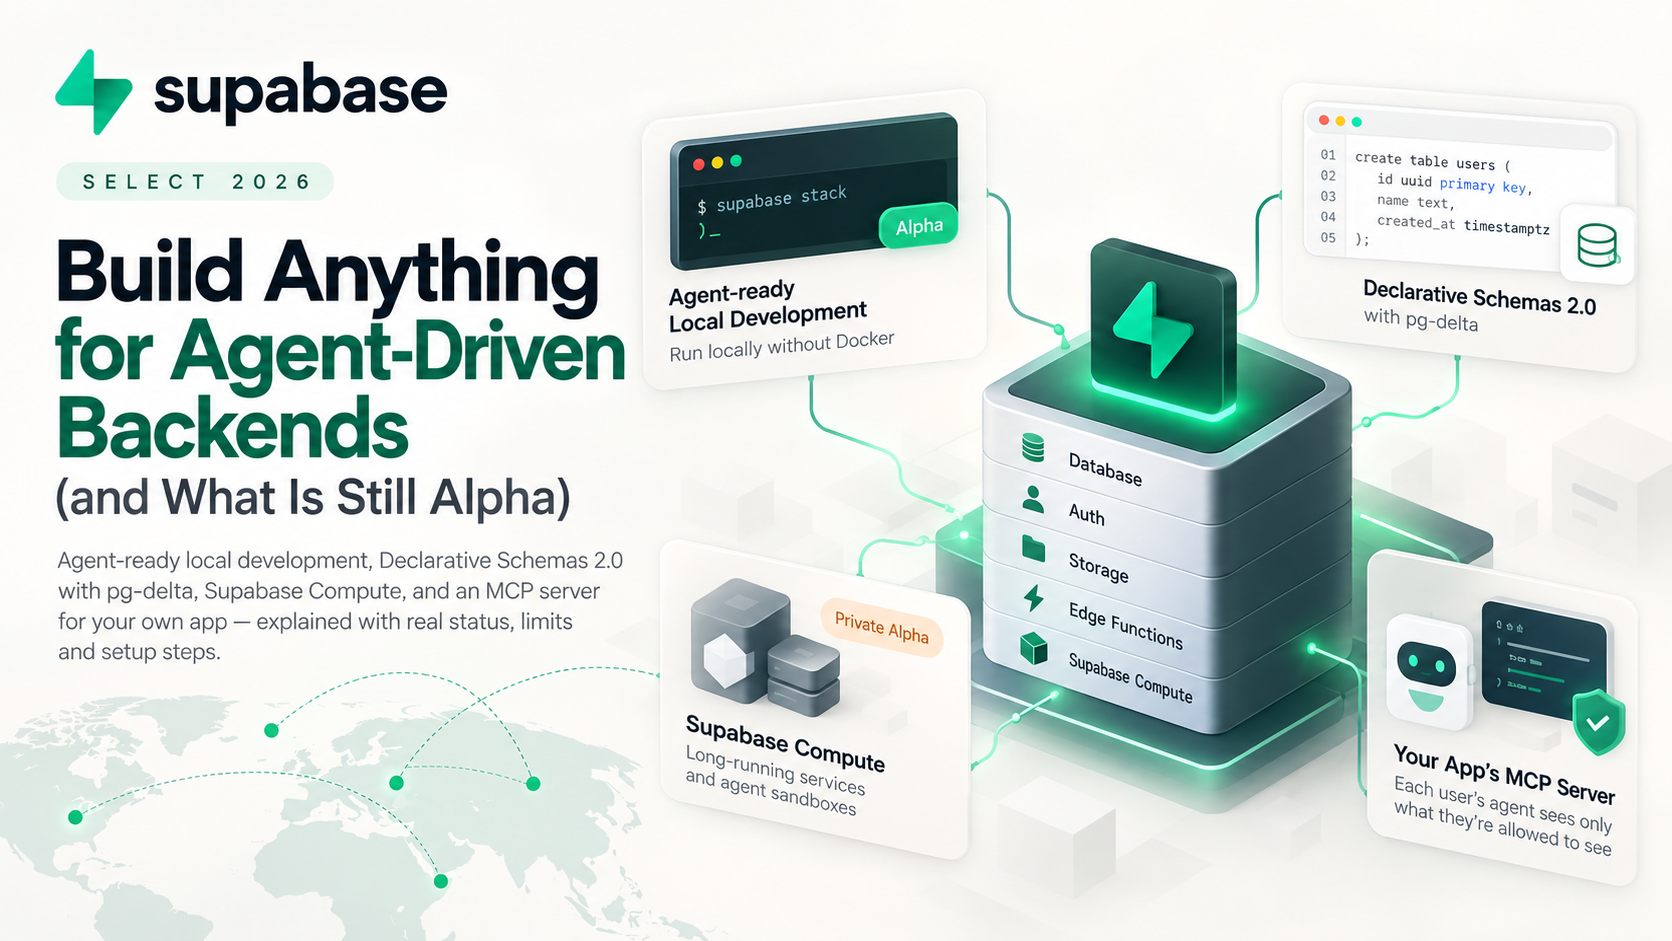
Summary. At Supabase Select 2026 on 2 October, Supabase announced four pieces aimed at letting coding agents build, test and deploy the backend, and letting your users' agents work inside your app. Their maturity varies a lot. Native local development without Docker is alpha and off by default, documented as experimental under the supabase stack commands, and runs only on Linux and Apple silicon Macs. Declarative Schemas 2.0 keeps your schema in SQL files and uses pg-delta, an open-source diff engine still in alpha, to write the migrations; new projects get it by default, and it never captures data or dashboard edits. Supabase Compute, long-running services and agent sandboxes beside your database, is a private alpha limited to us-west-2 projects and explicitly not for production. The MCP server for your app is a library block you install into an Edge Function, where each user's agent sees only what row-level security allows; it needs asymmetric JWT signing keys and Supabase Auth's OAuth 2.1 server, which is in beta. Our advice: try declarative schemas first, test native local development in CI, pilot the MCP block on a low-risk project, and only join the Compute waitlist.
About this article. eCorpIT is not affiliated with Supabase. Claims were checked on 23 October 2026 against Supabase's announcement and follow-up posts, its documentation, the Supabase CLI release notes and npm. Several features are alpha, experimental or beta, so commands and flags may change; confirm against the live docs before relying on them. Where we give our own reading rather than a documented fact, we say so. Researched with AI assistance and reviewed by our editorial team.
What Supabase announced, and the status of each piece
Supabase's case is simple: backend work used to happen in the dashboard, coding agents work in your repository, and dashboard edits never appear there. The four announcements move schema, settings and services into the repo, where an agent can change them.
| Announcement | Status | Main limits |
|---|---|---|
| Agent-ready local development (native runtime) | Alpha and off by default per the announcement; experimental supabase stack commands per the docs | Linux and Apple silicon only; not covered by the CLI compatibility promise |
| Declarative Schemas 2.0 with pg-delta | Default for new supabase init projects; opt-in for existing ones; pg-delta itself is alpha | Ignores data and dashboard edits; some object kinds untracked |
| Supabase Compute | Private alpha, waitlist | us-west-2 projects only; not for production or end customers |
| MCP server for your app | Library block, available now | Needs asymmetric JWT keys and the beta OAuth 2.1 server |
Supabase published other posts the same day, including Operate with confidence and the news that Supabase is acquiring Turso, which this article does not cover.
How agent-ready local development works
Until now, local Supabase needed Docker. The native runtime runs the same services as local processes, so it can start where there is no Docker daemon. The announcement names Claude Code's sandbox, Codex, Perplexity Computer and CI runners; on a machine with Docker, nothing changes.
It sits behind the experimental supabase stack commands, which first shipped in CLI v2.118.0 on 25 September 2026; the docs require v2.119.0 or later. Turn it on in supabase/config.toml, or set SUPABASE_EXPERIMENTAL_STACK=1 for a directory without a config file:
            [experimental]
stack = true
With the setting on, the CLI picks a runtime for each new local project: Docker if the daemon answers, then Podman, then native. Each check waits up to 10 seconds, and having the docker command installed is not enough. You can force one with --runtime docker, podman or native, the CLI never falls back from a forced choice, and the runtime is fixed for the life of that local project. Plain supabase start, without the stack setting, always uses Docker.
Platform limits. The native runtime supports Linux on amd64 and arm64 (Ubuntu 22.04 or later, or glibc 2.35 or later) and macOS 14 or later on Apple silicon. Windows and Intel Macs are not supported. It will not run as root, because Postgres initdb cannot, which matters in CI containers; SUPABASE_NATIVE_POSTGRES_USER is the documented workaround. On first start it downloads service archives from Supabase's slim-services GitHub releases, with an S3 fallback, so a sandbox with a network allowlist needs both hosts. Postgres starts at once, other services start on first request and stop after 60 seconds idle (Studio after five minutes), unless you pass --eager.
Running stacks side by side. The announcement says each directory gets its own stack, so an agent can test two changes side by side and keep the one that works. The docs define a local project's identity as its project root, its git branch and an optional --stack name. Different worktrees, branches or names get their own ports and data; two agents in the same checkout on the same branch share one. Ports come from 20000 to 32767 and stay stable across restarts, but ports written in config.toml are used as written, so remove fixed port lines.
Sharp edges. The db and migration commands do not accept --stack: db reset and db diff act on the current branch's default local project. Some settings are unsupported natively, including api.tls, a custom edge_runtime.deno_version and database major versions other than 15 and 17. Switching git branches switches local projects, and supabase stack destroy takes no backup. For comparison with dedicated agent sandboxes, see our AI coding agent sandboxes guide.
What Declarative Schemas 2.0 and pg-delta do
Supabase's argument is that agents are good at editing schema files and bad at writing migrations. In the new workflow, SQL files under supabase/schemas/ are the source of truth, and pg-delta generates the migration. Supabase covered it in a separate 13 October post, which notes it needs CLI 2.119 or later.
            # edit supabase/schemas/*.sql, then:
supabase db schema declarative sync -f add_age --no-apply
supabase start          # start the local database
supabase migration up   # apply the migration locally
supabase link           # once, to connect the remote project
supabase db push        # deploy to the linked project
Recent supabase init runs write the setting that turns pg-delta on. Existing projects add it themselves; without it they use the legacy migra engine, and the declarative commands refuse to run unless you pass --experimental for a single run. Supabase says the next major CLI version will make pg-delta the default for every project.
            [experimental.pgdelta]
enabled = true
The docs carry rules the announcement had no room for:
- Edit the files, not the dashboard. sync compares your schema files with your migration history and never reads the live database. A change made in Studio, the SQL editor or psql is invisible: the diff reports no changes and the edit is silently dropped.
- Do not use supabase db diff here. On pg-delta it diffs a live database against migrations and ignores supabase/schemas/.
- Baseline existing projects. Export the production schema with supabase db schema declarative generate --linked. If you have no migrations, run supabase db pull first; otherwise the first sync regenerates the whole schema as one migration that can apply locally and still fail on db push.
- Data is never captured. Insert, update and delete statements are outside a schema diff, including storage buckets, which are rows in storage.buckets. A DML statement in a declarative file is an error. Named pg_cron jobs and pgmq queues are tracked separately through extension functions.
- Some object kinds are untracked. Casts, operators, text-search objects, languages, transforms and a few others produce warnings, which --strict-coverage turns into CI failures. In the Supabase-managed auth and storage schemas, only your RLS policies and triggers whose function lives elsewhere are captured.
- Review every migration. Generated migrations can include GRANT and REVOKE lines reflecting default privileges, and a renamed column comes out as a drop followed by an add, which loses data if you apply it blindly.
pg-delta is open source under the PostgreSQL License, written in TypeScript, lives in Supabase's pg-toolbelt repository, supports Postgres 14 to 18, and is published on npm as a 1.0 alpha.
Settings in config.toml. The announcement says settings such as auth providers, API limits and storage buckets live in config.toml, that supabase config pull brings a dashboard change back into the file, and that supabase pull fetches config, schema and Edge Functions in one go. The CLI release notes show supabase pull from v2.118.0 and config pull by v2.120.0, but neither appears yet in the CLI reference, so check your CLI's help. Note the asymmetry: config pull handles settings, while dashboard schema edits are never picked up by sync.
What Supabase Compute is, and whether you can use it
Compute targets work Edge Functions cannot do: agents, embedding jobs over large file sets, always-on services and sandboxes. The announcement says services run without a time limit, you choose CPU and memory, and each gets a full Linux environment. You deploy from the CLI, manage services through the Management API, define them in config.toml, and get the same default environment variables as an Edge Function. A service can have a public HTTP URL or be private, for jobs like a queue consumer, and network restrictions can limit database access to your Compute instances.
The product page adds Supabase's own claims, which we have not tested: each workload runs in its own microVM with dedicated CPU and memory, queries over the same network as Postgres take single-digit milliseconds, idle services suspend and resume in under a second with no charge while asleep, and secrets can be scoped per workload and optionally cloaked so your code never sees them. Its FAQ says billing will be per compute-hour by instance size with no per-request metering, traffic to the workload's own database is free, final rates come before general availability, the local filesystem is scratch space, and persistent disks are on the roadmap.
Status is the key fact. Compute is a private alpha behind a waitlist, open only to projects created in us-west-2. The waitlist terms say it is provided as is, for internal evaluation only, must not serve production workloads or your own end customers, may change or end without notice, and may never become generally available. Join the waitlist if you are curious, but do not design a product around it yet.
How the MCP server for your app works
MCP, the Model Context Protocol, is the standard that lets agents act in an app on a user's behalf. This block is separate from Supabase's official MCP server, which helps you build your app; this one lets your users' agents work inside it.
The announcement installs it with supabase pull and then a shadcn command for @supabase/mcp-server. The block's own page now uses the shorter name, and the old one redirects:
            supabase pull
npx shadcn@latest add @supabase/mcp
You own the code it adds: an authenticated Edge Function built as a pipeline from @supabase/middleware with two entries from @supabase/server. One serves OAuth protected-resource metadata (RFC 9728) so MCP clients can find the authorisation server; the other, withSupabase with user auth, verifies the caller's token and hands your tools an RLS-scoped client. It accepts two callers: your own product backend forwarding its signed-in user's Supabase access token, and external clients such as Claude Code, Codex and ChatGPT, which authenticate through OAuth so users approve and revoke each one separately. Each tool is a small module, and the shared context deliberately excludes the admin client.
Prerequisites. The project must sign JWTs with an asymmetric key, ES256 or RS256, because the block verifies tokens against the project's JWKS and rejects legacy HS256 tokens; switching is a project-wide change in the JWT signing keys settings. You also need Supabase CLI 2.117.0 or later, @supabase/server 1.6.0 or later (1.9.2 is current), JWT verification turned off for the function because it verifies tokens itself, and, for external clients, the Supabase Auth OAuth 2.1 server, which is in beta, with a consent page from the separate OAuth Consent block.
            [functions.mcp]
verify_jwt = false

[auth.oauth_server]
enabled = true
authorization_url_path = "/oauth/consent"
allow_dynamic_registration = true
Supabase walked through the block in more detail in a 22 October post. The announcement also mentions a headless app template, a backend with an agent as its main interface, which we have not evaluated.
How to secure an app MCP server
An MCP server is an authenticated door into your product, and the block's documentation is direct about the risks:
- Treat it as a normal authenticated API. Anyone holding a valid user token can call the function directly. Keep RLS on, check authorisation for business operations, and never add admin clients to the tool context.
- OAuth scopes control identity, not data. Scopes do not decide which rows or tools a client can reach. Use the client_id claim for client-specific policies, and decide how product sessions, which have no client_id, should behave.
- Never authorise on user-editable metadata.
- Keep tokens out of prompts. For embedded product agents, hold the user's token in your backend and never pass it to a model provider.
- Decide on dynamic registration. The block's example allows any compatible client to register itself; set allow_dynamic_registration to false if you register clients yourself, as Supabase's own OAuth getting-started example does.
Our reading, not Supabase's: this design makes RLS the security boundary, which is only as strong as your policies. Review them as you would a public API before exposing agent tools. Our guides to MCP authentication and MCP server hardening cover the wider threat model, and the MCP stateless spec migration guide covers protocol changes.
What this means for Flutter and mobile teams
This section is our interpretation. None of the four features changes the client libraries your Flutter or mobile app uses; they change how the backend is built, tested and exposed.
Schema-in-repo suits teams that keep app and backend in one repository: an agent or developer edits a SQL file and the migration follows. The catch is process, because everyone has to stop making schema changes in Studio. The MCP block is a backend feature in an Edge Function, separate from the app users install, and letting users' agents act in your product is a product decision as much as a technical one. Moving to asymmetric JWT keys affects anything that verifies Supabase tokens, including custom backends, so check those first. Native local development could remove Docker from CI runners, but test it on a branch. Our Flutter app development team works with Supabase backends if you want a second opinion.
Should you adopt these features now?
In order of readiness:
- Declarative schemas on a new or low-risk project. Read every generated migration, watch for renames, and write down the files-not-Studio rule. For cost and scaling decisions around the database itself, see our Supabase read replica cost model and Neon vs Supabase comparison.
- Native local development in a throwaway CI job or sandbox. Pin the CLI version and expect flags to change.
- The MCP block on a non-critical project, after reviewing RLS policies and the effect of switching JWT signing keys, and with the OAuth server's beta status in mind.
- Compute: join the waitlist and wait. It is not offered for production use.
Add evals for any agent-facing tools before launch, as our guide to agent evals in CI/CD describes. If you self-host Supabase, our self-hosted Envoy gateway runbook covers recent breaking changes there.
Open questions
We could not establish when the native runtime and supabase stack commands leave experimental status, when the CLI reference will document supabase pull and config pull, what Compute's final rates and region list will be, how the headless app template behaves in practice, or how pg-delta handles edge cases beyond its documented caveats. Supabase's changelog and CLI release notes are the places to watch.
How eCorpIT can help
eCorpIT is a Gurugram-based technology organisation, founded in 2021, assessed at CMMI Level 5 and MSME certified, with senior-led engineering teams working across AWS, Microsoft and Google platforms. Our MCP server development service designs and builds MCP servers for products, including Supabase-backed apps, with RLS reviews, OAuth set-up and tool-level authorisation. Talk to us at /contact-us/.
Last updated: 23 October 2026.